“For 60 overs, they should feel like hell out there.”
Published:
Originally published on Beyond the Box Score on Substack.
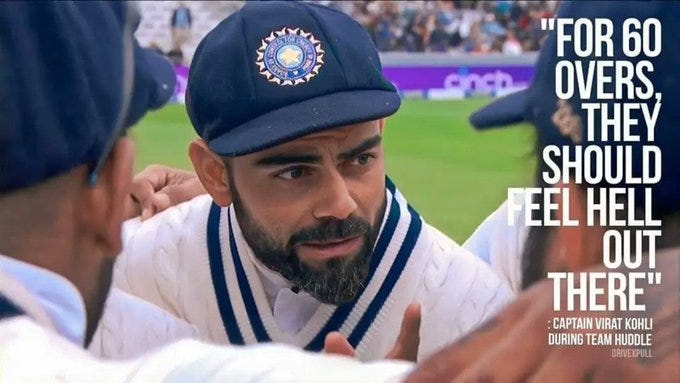
Avid fans of the Indian Test team will be quick to point out that this quote comes from Virat Kohli, as he and his men took the field for the fourth innings after a declaration in the 2021 Test at Lord’s between India and England. What happened next was shocking; one of the largest single-day turnarounds in the last 50 years of Test cricket followed.
England were rattled 120 all out with Siraj and Bumrah picking up 7 wickets between them. However, the focus point when one brings up this match shifts between KL Rahul’s 129, Shami and Bumrah’s unlikely 89-run partnership, and the fourth-innings effort that is often brought up with Kohli’s name.
Despite not bowling a single ball and scoring a measly 11% of his team’s runs batting at #4, this match is brought up as Kohli’s crowning achievement as captain of the Indian Test side. As an analytical mind, the natural next step was to wonder: “How much of this can actually be attributed to Kohli? How can we quantify it?”
I attempt to explore the question of the effect of captaincy in Test cricket as best I can with the help of Himanish Ganjoo’s Ball-by-Ball dataset with line/length, Bhuvanesh Prasad’s Test match dataset, and Cricinfo data. If you enjoyed it, subscribe on Substack and share my work with your friends! :)
Data Overview
The data comes from 3 sources. The ball-by-ball data contains line/length, country, and game state features (bat runs/balls faced, bowler wickets/balls faced, innings, innings runs/overs, day, session, bat hand, bowl style). Cricinfo’s data includes innings-by-innings records for all players, which can be joined to infer player quality/form. The match dataset includes information on who the captain is for all matches from January 1, 2005, to May 2024, which is the time period of analysis for this dataset.
Feature Preparation
The idea behind the feature engineering is that we want to see the current game state and adjust for the quality of the players and the current match context, i.e., “What is the captain looking at right now, and what did he do beyond what was already in front of him?” We don’t want a captain rewarded for having Mitchell Starc and punished for a subpar attack. This is where line/length comes in, as, along with bowler/batting quality proxies, we can estimate the expected outcome of each ball. With the game state and information about the ball, the match residual can be used to estimate the persistent impact that a captain has on the game over the course of their captaincy.
From the Cricinfo data, a Bayesian prior is calculated for each player’s average and strike rate before the match to estimate player strength. Note for bowling, the strike rate is the average number of balls it takes to get a wicket, while for batting, it’s simply 100 * runs/balls. They are different statistics. For batting and bowling averages, the same formula is used:
\[Avg_{post} = \frac{k * \mu_{average} + R} {(k + W)}\]Where W is the amount of dismissals/wickets for a bowler, and R is the runs before a match. Mu is the population average for that statistic during the corresponding calendar year. The more we learn about a player, the more the prior converges to the true average. For batting and bowling strike rate, where B is the amount of balls a batsman faces or a bowler has bowled before a match:
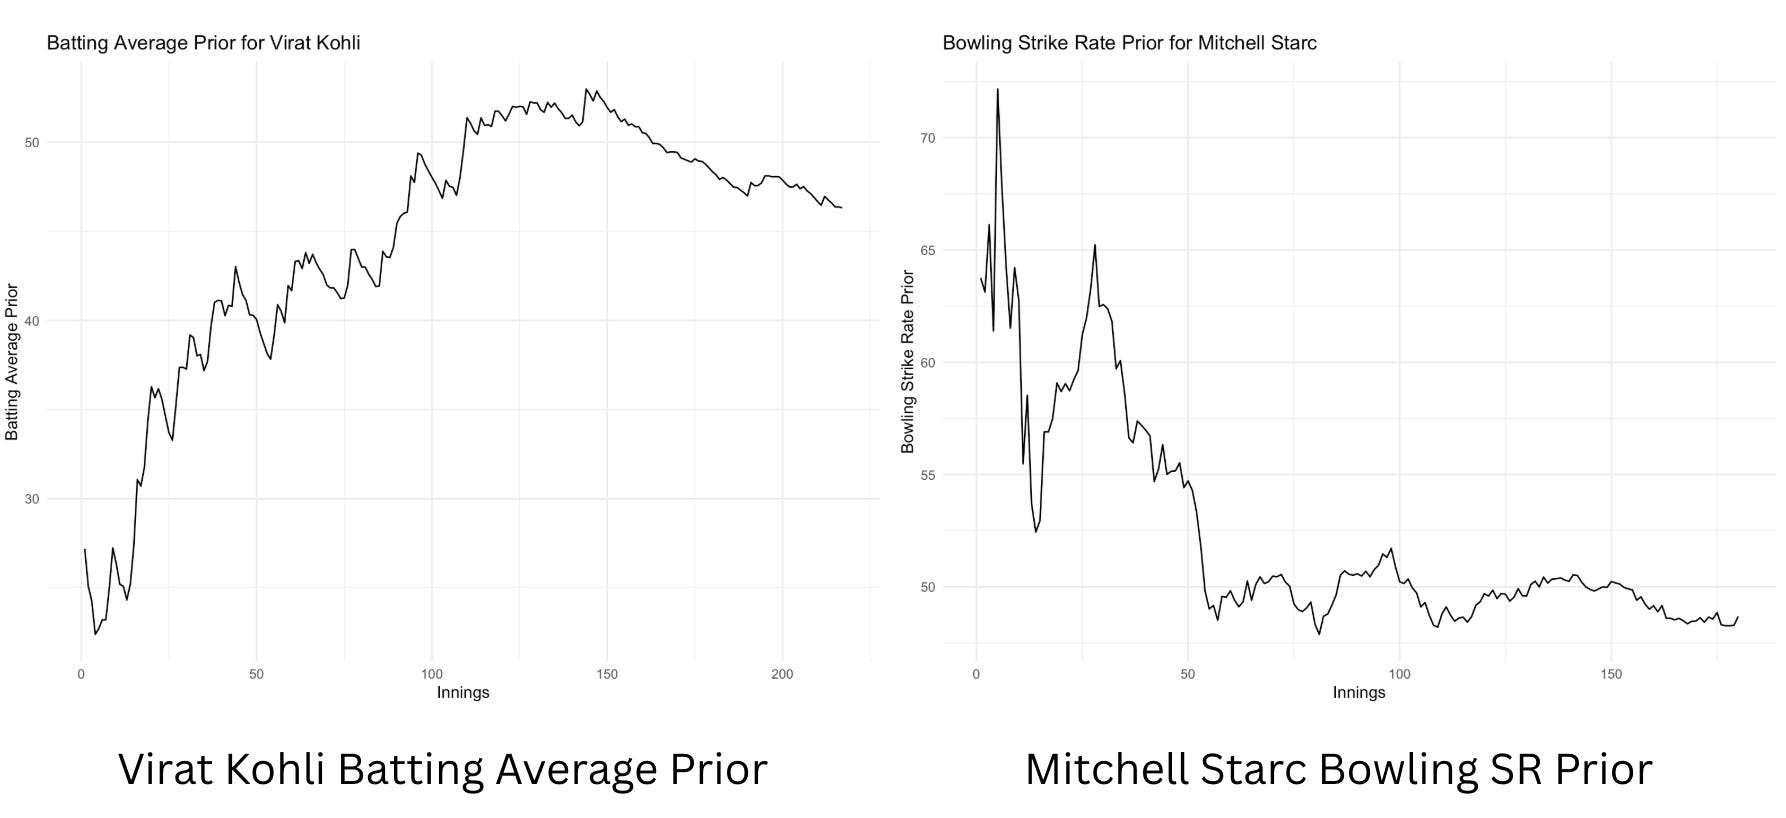
\[Batsr_{post} = \frac{k * \mu_{batsr} + 100 * R}{k + B}\] \[Bowlsr_{post} = \frac{k * \mu_{bowlsr} + R}{k + B}\]In the examples of Virat Kohli’s batting average and Mitchell Starc’s bowling strike rate, you can see the averages fluctuate early in their careers, but as they become more established players, the priors become consistent with their career averages to that point. Experience is also treated as a feature, shared as a log transformed value of the number of innings a player batted/bowled in.
Expected Runs/Wickets Models
To model expected runs and wickets, two separate XGBoost models are trained on all the features. Runs are treated as discrete outcomes and in classes - 2s and 3s were one class, and the small number of 5s were placed into 1s class as they come from overthrows on a single. Both models were trained for 200 boosting rounds using the full set of encoded predictors derived from the engineered features.
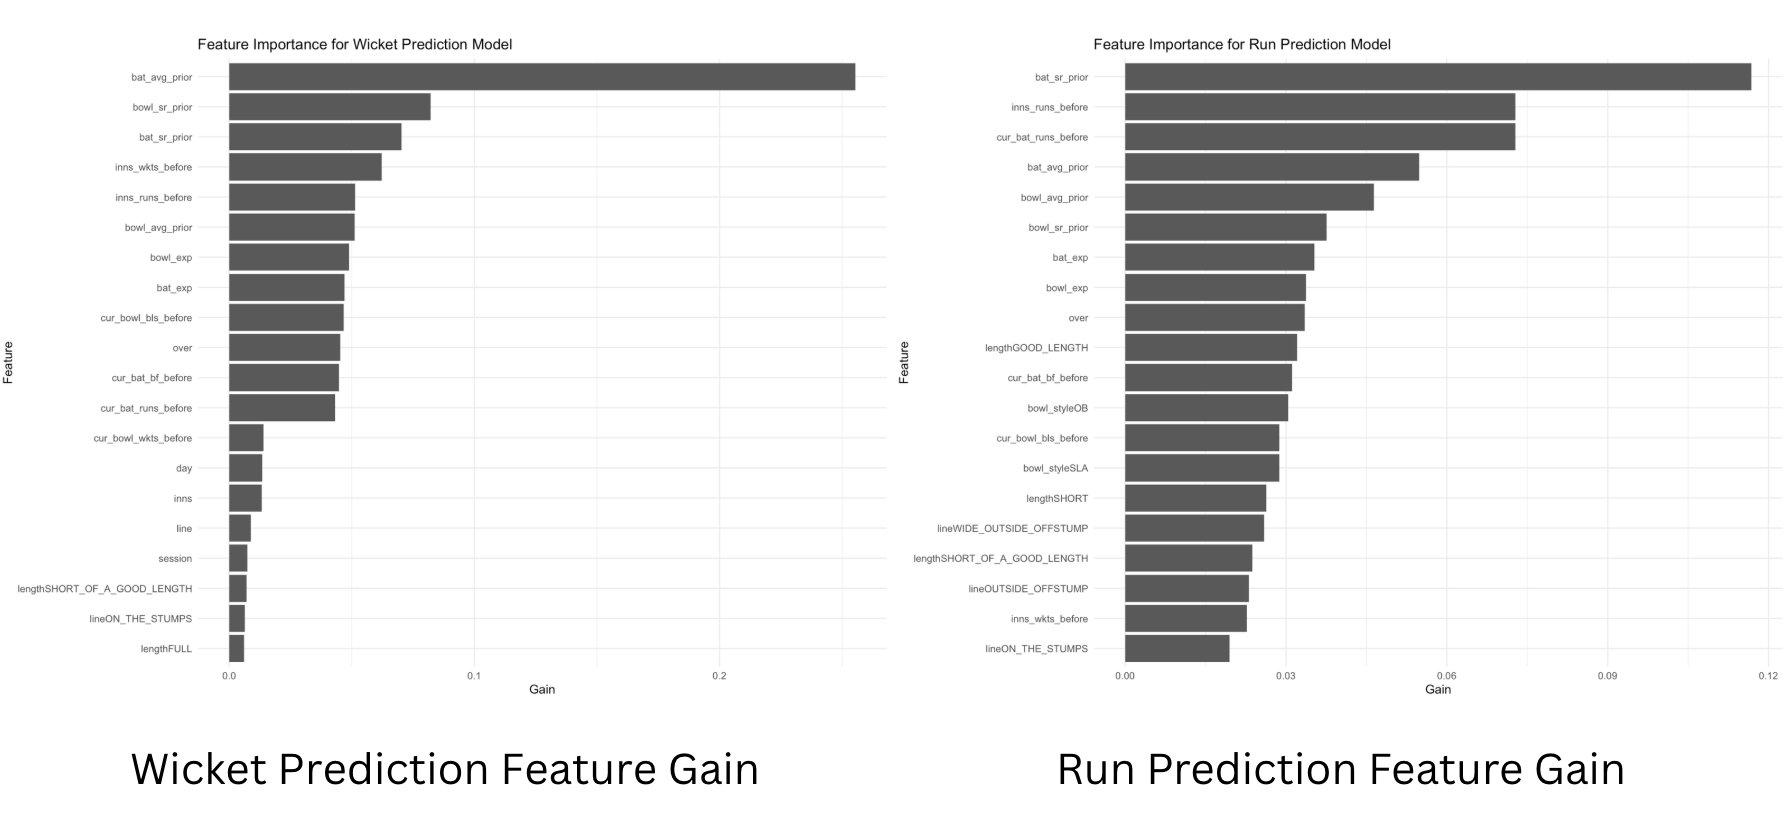
The feature importance plots are shown, with some interesting takeaways. The batting average and bowler quality are the most important features, as well as the innings state - the model recognizes that wicket probability changes as batsmen keep going, or as one gets into the tail. Moderate gain is also present in the amount of balls a batsman/bowler have been involved in.
In the expected runs model, line/length are much more important (for example, the gain in the outside off-stump line is most likely due to players leaving). Batting strike rate is expected to be the most important feature, as it quantifies the batter’s aggressiveness. In addition, as an inning progresses, the model recognizes batsmen are looking to score more. Player experience is also much more of a factor in this model, likely because experienced players know how to plan when going for/restricting runs to balance run-scoring/prevention with wicket taking/protection.
Empirical Bayesian Shrinkage of Residuals
Once expected runs and wickets are available, to analyze the persistent effects of captains, empirical Bayesian shrinkage is used. For wickets and runs, an empirical Bayes shrinkage estimator was applied directly to each captain’s average match residual as a linear mixed-effects model estimated essentially zero between-captain variance. This means the units of each effect are easily interpretable - wickets taken above/below average and the same for runs conceded.
It’s important to note that in a game-planning sense, captains are trying to take wickets and ~33 runs are worth one wicket in Test cricket, so captains are willing to let 10 runs go if it means it’ll increase the chances of getting a wicket. This planning, especially at the top order, is an ever-changing optimization problem that captains have to deal with. If a captain can take wickets while balancing the amount of runs they let go, then their ability is truly exceptional. The effect of this balance is that you have a residual estimate of each captain’s ability in both facets that looks like this:
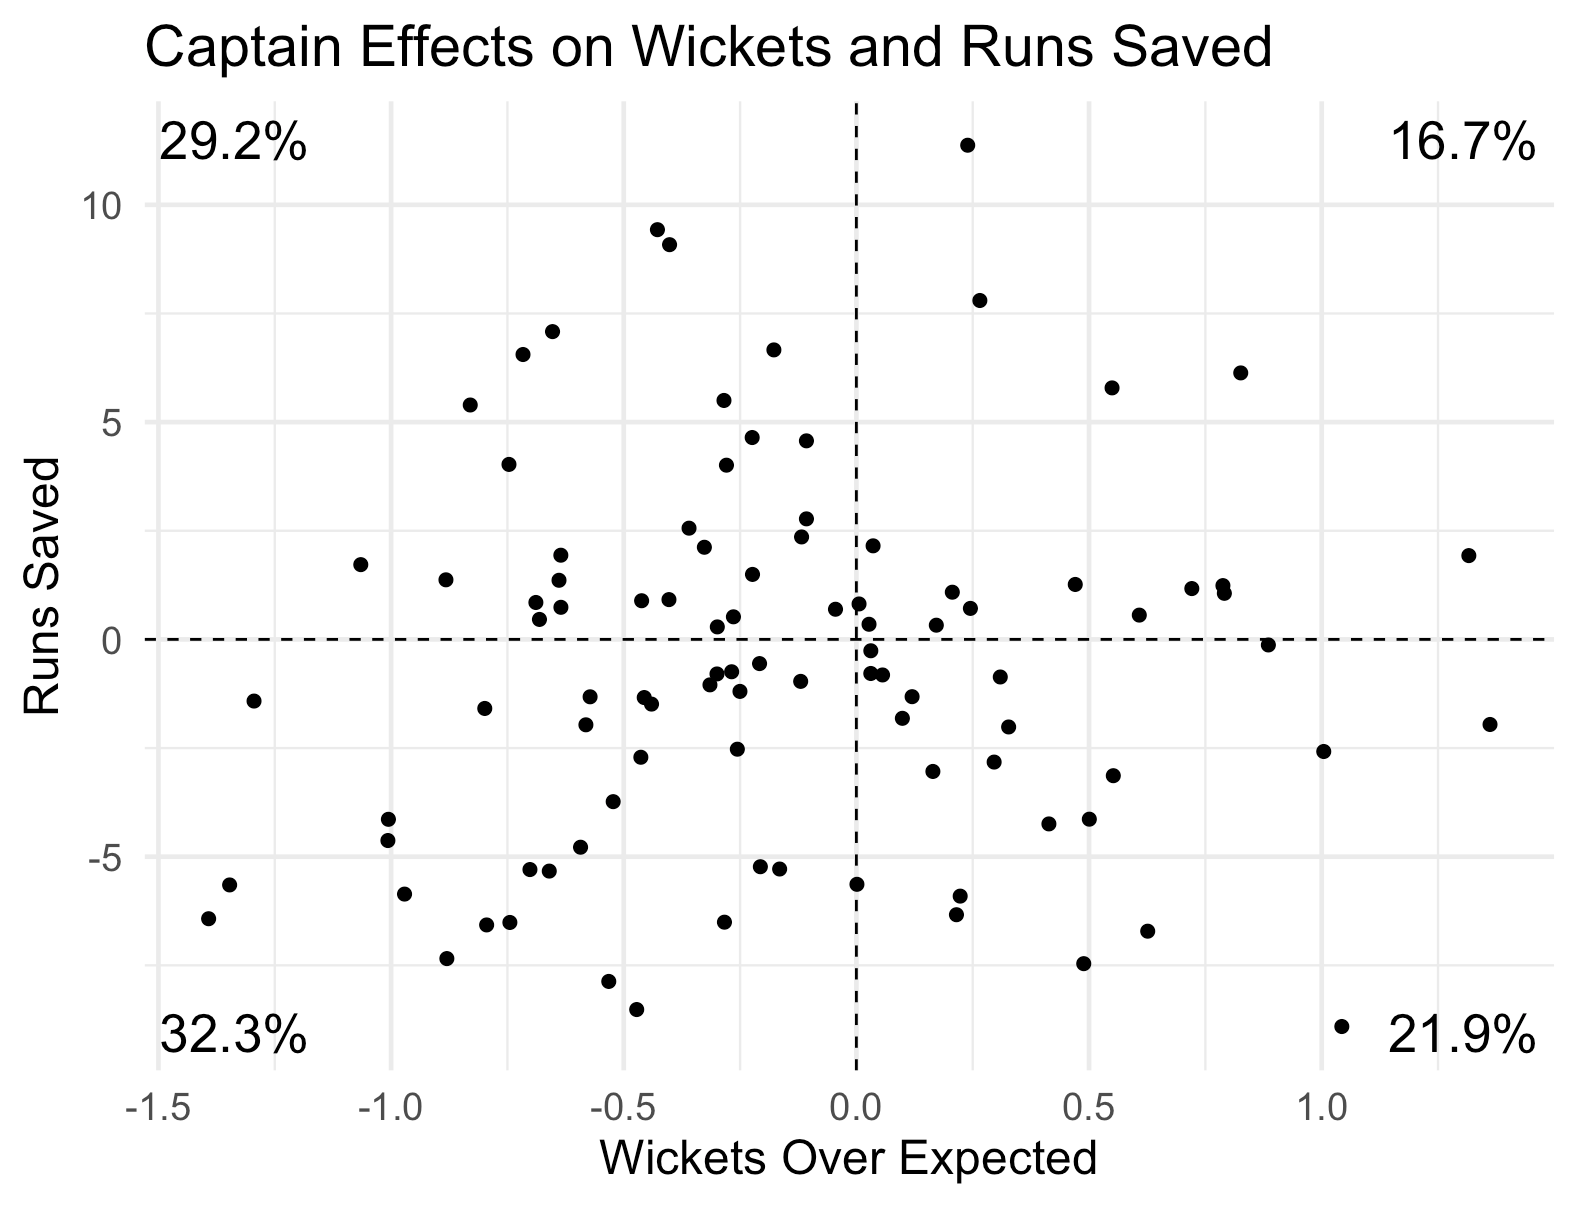
The estimates here are the persistent effect that a captain has on wickets taken and runs conceded beyond what would be expected given the match context and the quality of the players involved. What pops out is that top-right quadrant is where most captains want to be - conceding less runs and taking more wickets than average, but only 16.7% of captains end up in that quadrant. Almost 2/3rds of the captains also have a negative wicket effect, meaning they consistently took fewer wickets than the model expected.
There also is little to no association with these effect sizes and the amount of matches captained. There is weak evidence that more experienced captains tend to save slightly more runs than expected (r2 = 5.6%), while there is no clear evidence that simply captaining more matches leads to better-than-expected wicket taking (r2 = 3%), with n = 96.
I also wanted to address one of the points on the left of the scatterplot, as it happens to be Graeme Smith with a wicket effect of -0.63. Obviously, he was not a bad captain by any stretch of the imagination; the South African team was fearsome with Steyn, Morkel, Philander, and Kallis, but that’s just it. Smith’s slightly negative residual indicates that, relative to the already high expectations set by his bowling attack, his teams took marginally fewer wickets than predicted. In other words, the model is evaluating performance relative to the strength of the bowling attack, not absolute wicket totals.
Coming back to the Lord’s 2021 example: there were 6.69 expected wickets in the fourth innings, meaning ~3.3 wickets were taken over expected, which is a lot. In all 4th innings in the data, 3.31 is in the top 8.6% of wickets over expected. The empirical Bayes model allows us to assign roughly a quarter of this residual to Kohli’s estimated captain effect. Across many matches, Kohli’s teams consistently outperform their expected wicket totals after accounting for player quality and match context, providing evidence of a persistent captaincy effect - this match is just one point of evidence.
Top captain ratings, the interesting part…
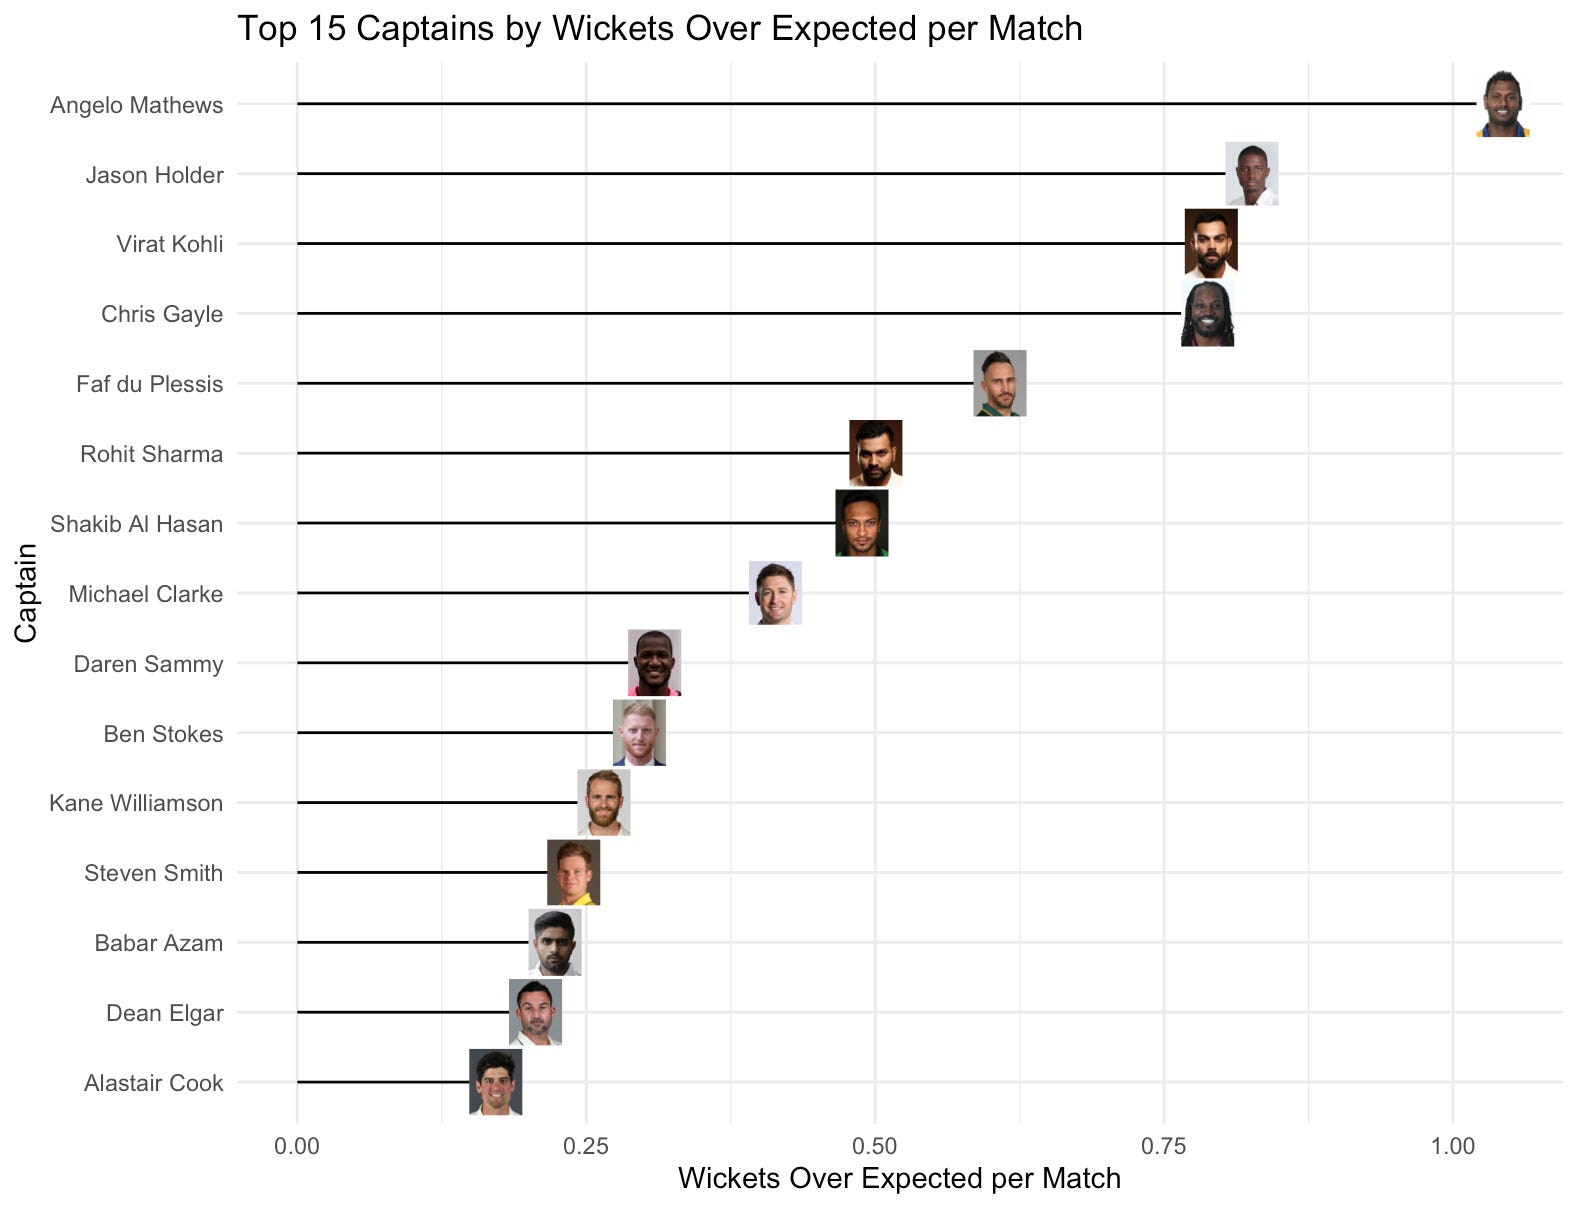
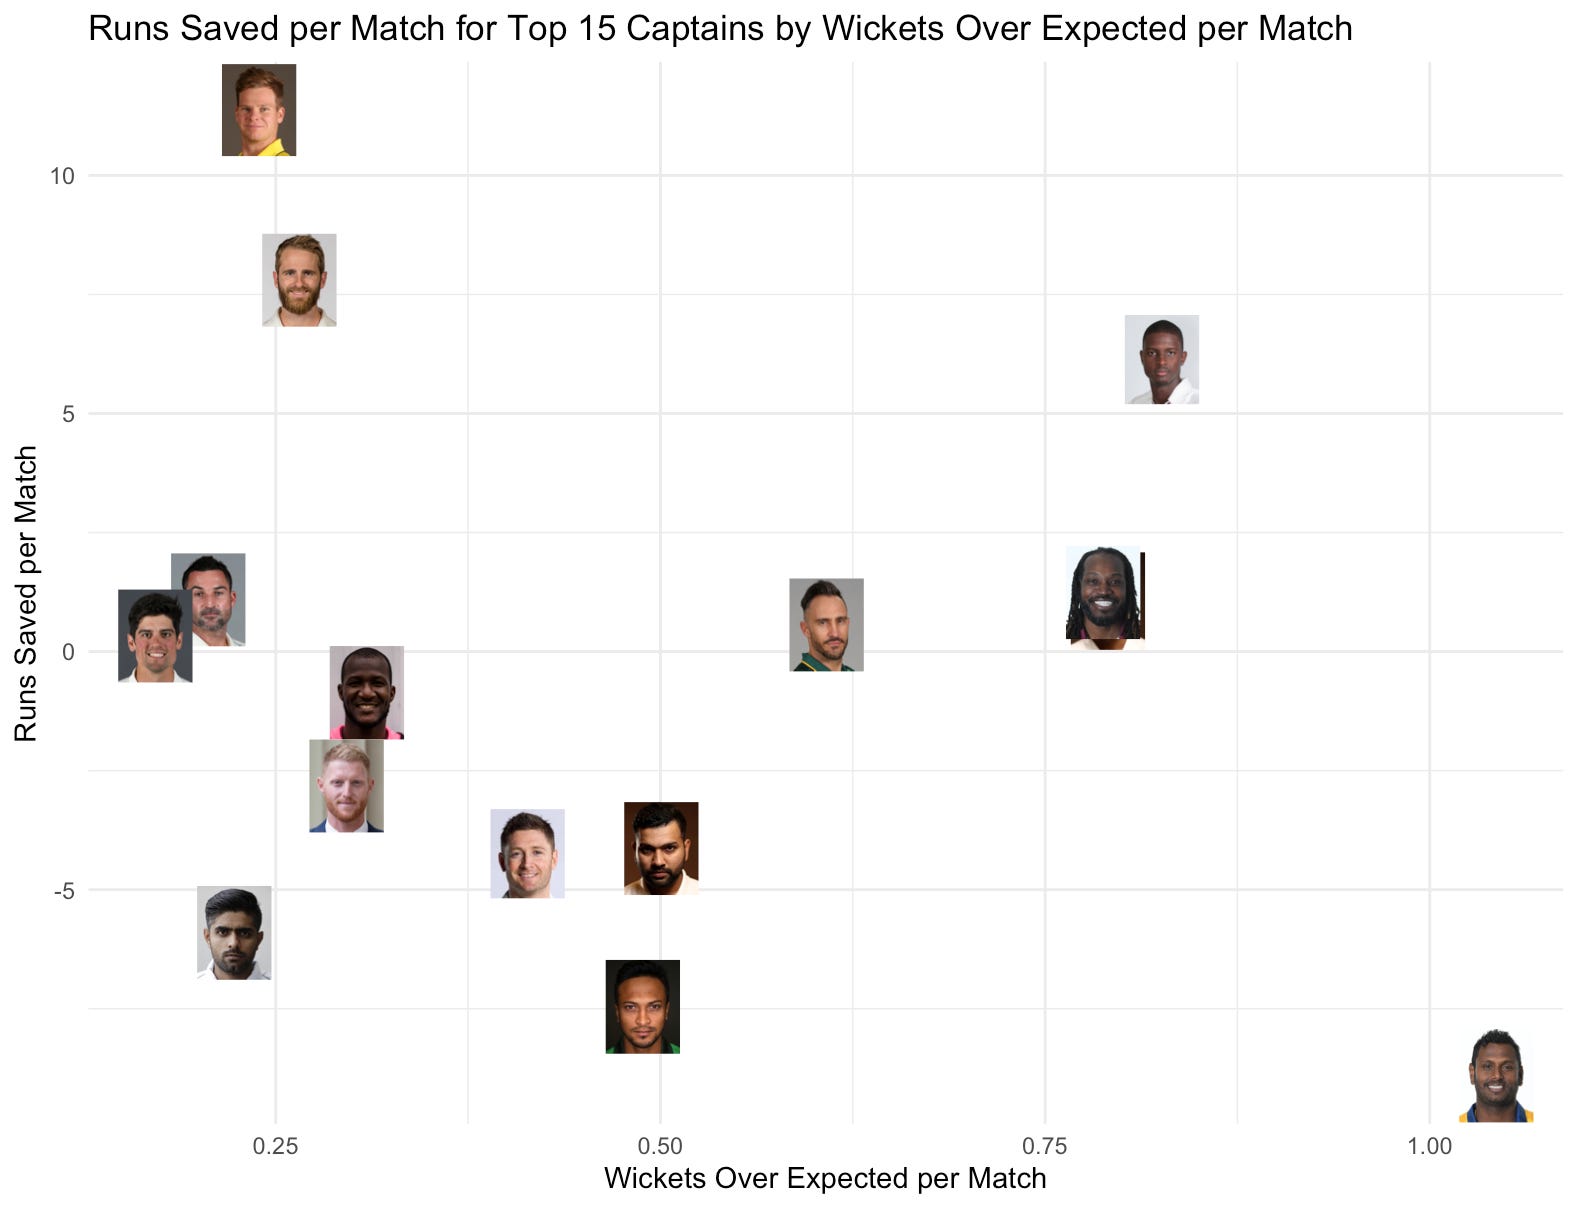
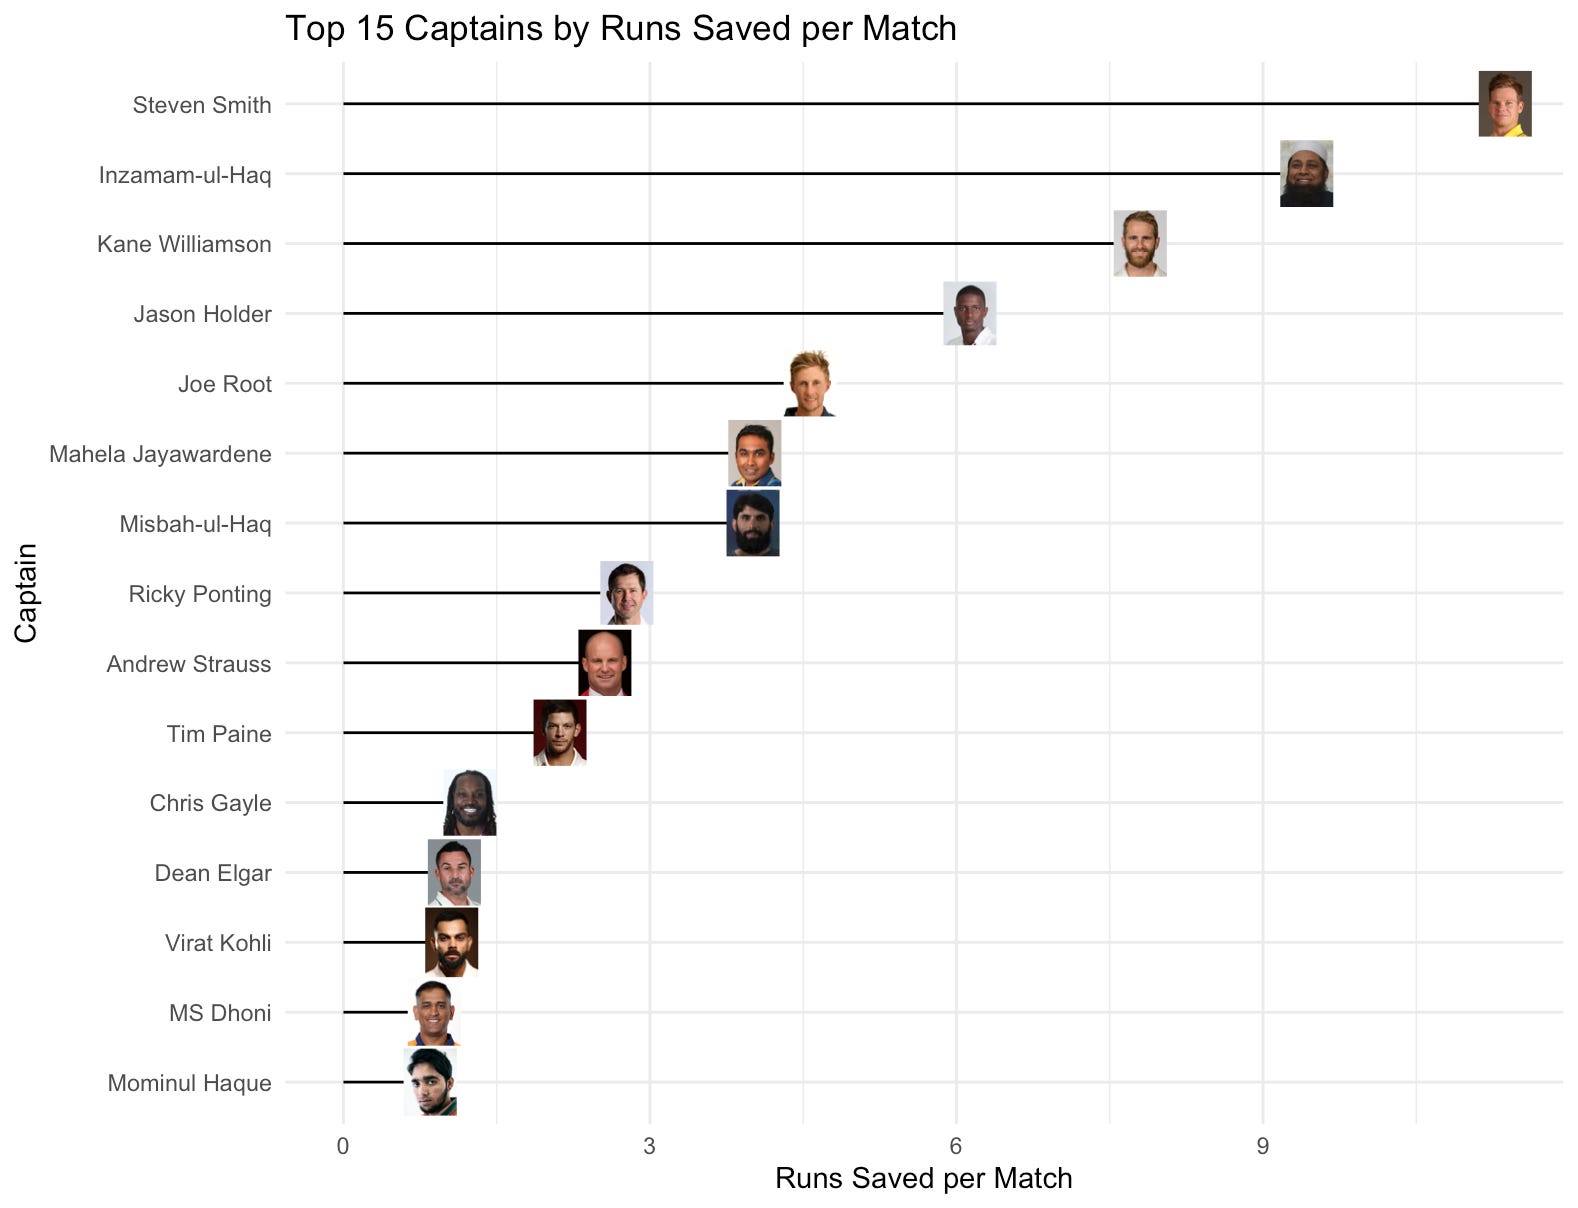
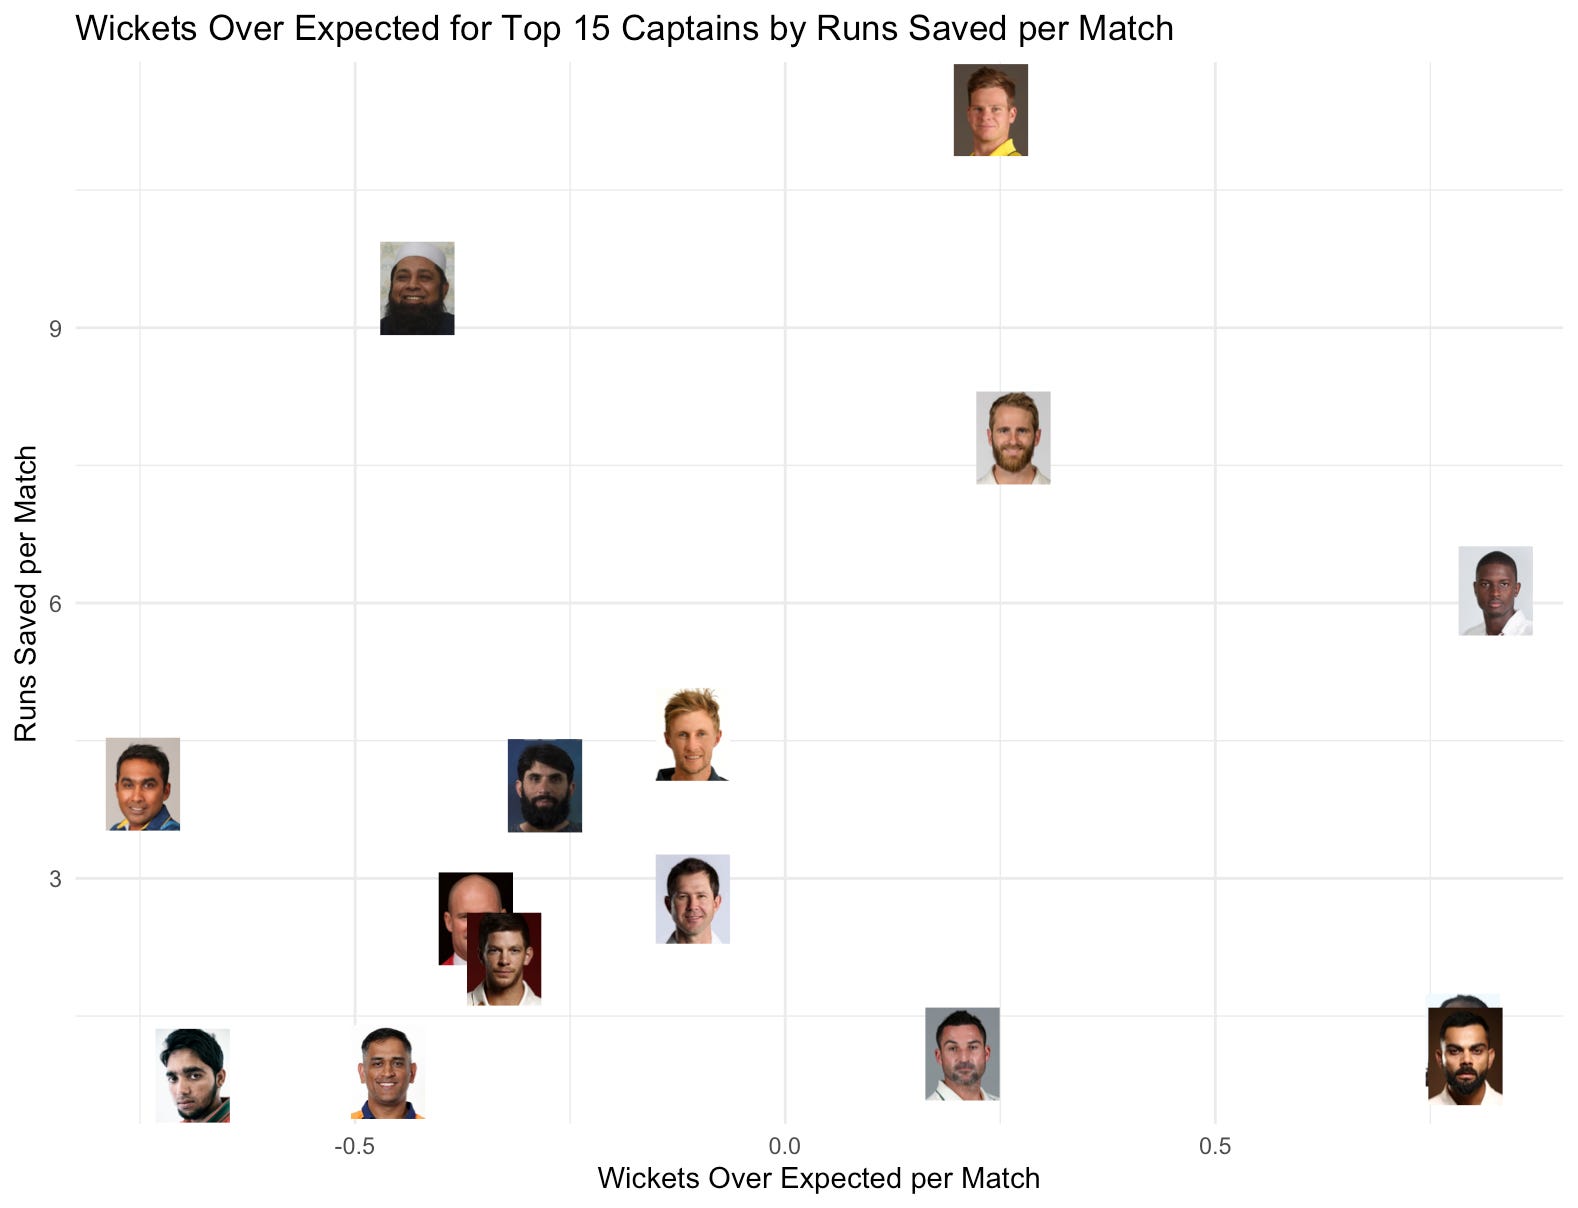
Lastly, I wanted to leave you with the top 15 captains by their wicket/run effects. The plot of their wicket effect is shown, as well as their corresponding run effect, and vice versa. I could address specific captains, but I think it would be more fun to hear what you think of the top captains in the comments!
The one I will address is Jason Holder - for the squads he was given, he was able to extract consistent effects in runs and wickets. He lost his captaincy due to some politics with the WICB after missing one series due to COVID concerns, which obviously this model doesn’t take into account ;) Quantitatively, Holder is one of the best captains in the last 20 years while his replacement Kraigg Brathwaite doesn’t come close.
What’s missing + Thanks for reading!
This doesn’t take into account any impact of a captain’s DRS accuracy or other decisions like declaration timing - in that same England vs. India match, Kohli got two not-outs for LBW overturned, getting Bairstow pad-first and ending Robinson’s resistance with the rest of the wickets falling shortly after. In addition, he declared 9 balls into the second session, not at lunch, which did not allow the batters the hour to prepare for the first ball. Partly due to that, both openers fell within the first two overs. This is consistent with the model estimating a strong positive residual in that innings, although it should only be treated as an illustrative example rather than direct evidence of a 3.3-wicket captaincy effect.
In addition, off-the field issues, heavy scrutiny in the public eye, and selection politics come with the Test captaincy, especially in India, Australia, and England. I mentioned Jason Holder’s situation despite his excellence as skipper and overall maturity even as a younger captain. Recently, Ben Stokes has resigned his captaincy post and even retired from international cricket following a nightclub incident with Gus Atkinson and a rugby team. As recent events have shown, there’s a lot more than what happens on the field that goes into becoming and maintaining Test captain. There is also the issue of captaincy hampering individual performance, as for example, Virat Kohli’s batting average in Tests dipped near the end of his captaincy and continued to decline until 2024 when he retired from the format.
Speaking of Virat Kohli: his wicket effect of 0.79 is an average estimate based on all the data available - it’s much more robust and is built upon years of data. He may have been partially responsible for 3 wickets in one match, and been the reason India didn’t take 2 in the next. India may have had a hundred problems as the variation between matches shows, but captaincy wasn’t one of them with Kohli. For him, as well as the other Test captains in the data, it has a small effect on average, but it adds up over time and very well may have been the difference in many games with similar quality on both sides. Hope you enjoyed reading!
Hi I’m Archith! Subscribe on Substack if you love sports and numbers, you’ve made it this far :)